
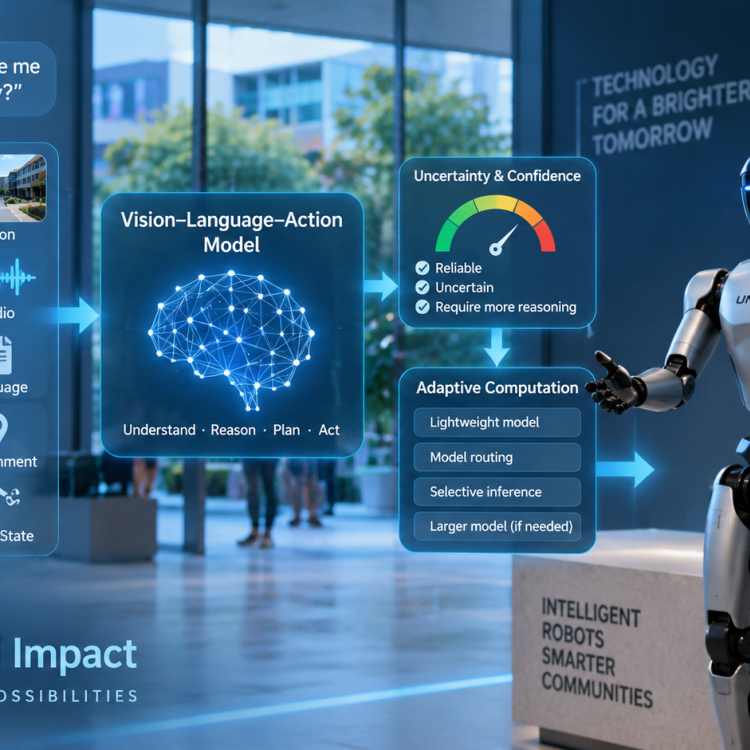
Vision-Language-Action (VLA) models are changing the way robots perceive their surroundings, interpret instructions, reason about tasks, and interact with the physical world. By bringing vision, language, and action into a common framework, these models offer a promising route towards robots that can operate more naturally in complex and unfamiliar environments.
Research projects in Information Technology
Displaying 1 - 10 of 123 projects.

[Malaysia Campus- VPSSP] An AI-Informed Planetary Health Framework for Equitable AMR Risk Mitigation
This project develops an AI-informed, community-grounded framework to understand and mitigate antimicrobial resistance (AMR) risks within a planetary health context. Building on the risk modelling from Project 1, we will conduct focus groups and interviews with communities in high- and low-risk zones to capture local knowledge, behaviours, and risk perceptions related to AMR.
Supervisor: Dr Sicily Fung Fung Ting
Longform generation and multimodal learning for Biomedical NLP
Large language models increasingly adapt using external feedback to alter inference-time behaviour, persistent state or model parameters. However, the signals that drive these changes may be noisy, biased, incomplete, delayed, correlated with the model’s own errors, or progressively underused during long-context and multi-step processing. This project studies reliable adaptation as a general feedback-mediated problem by distinguishing failures at the feedback source, during signal transmission and during model updating.
Supervisor: Assoc Prof Sarvnaz Karimi
Bioinformatics analysis of spatial data in congenital heart diseases
Congenital heart disease affects 1 in 100 babies. Spatial gene expression patterns are critical to understand how the heart develops and what underlying genetic patterns are behind heart malformation. High-throughput spatial temporal data have been recently generated with spatial transcriptomics technologies. Capitalising on these rich datasets, we aim to build a custom analysis workflow in which the cells are profiled with precise spatial gene expression information. The student will provide fundamental contribution to of this project, by:
Supervisor: Assoc Prof David Dowe
[Malaysia] - Foundation Models for Graph Representation Learning in Medical Artificial Intelligence
Graph learning has become one of the most successful approaches for analysing complex biomedical data such as brain connectivity networks, molecular interactions, and patient similarity graphs. However, most existing graph neural networks are developed for individual diseases or specific datasets, limiting their ability to generalise across different clinical applications.
Supervisor: Dr Fuad Noman
[Malaysia] - Trustworthy Agentic Artificial Intelligence for Explainable Medical Decision Support Systems
Artificial Intelligence is rapidly transforming healthcare by assisting clinicians in disease diagnosis, prognosis, and treatment planning. While recent advances in deep learning and large language models (LLMs) have significantly improved predictive performance, most existing AI systems remain passive prediction tools that lack transparency, reasoning capability, and reliability. These limitations hinder their adoption in real-world clinical practice, where explainability, trust, and accountability are essential.
Supervisor: Dr Fuad Noman
Verifiable, Uncertainty-Aware World Models as Safety Guardrails for AI Agents
The rapid deployment of increasingly capable AI agents has prompted a fundamental reassessment of how safety should be built into AI systems. Bengio and colleagues have argued that purely agentic training objectives are intrinsically risky and have proposed an alternative paradigm: a non-agentic "Scientist AI" that explains the world from observations rather than acting in it, combining a world model that generates explanatory theories with a question-answering inference machine, and operating with explicit notions of uncertainty so as to mitigate overconfident predictions [1].
Supervisor: Dr Lizhen Qu
Being Bayesian about Large Language Models to Address Truthfulness
Several explanations for hallucination exist, but perhaps the main reason is that they are trained to be plausible. There is no element of truth-seeking in their construction. The training content can be filtered to support this, but in many areas truth is not established. Many text sources are opinions, may contain argumentation and indeed subtle or not so subtle propaganda, written in many dfferent styles, and some reflect misinformed views. Even Wikipedia sources are known to have bias (so called "establishment bias").
Supervisor: Prof Wray Buntine
Audio captioning using machine learning
This project involves the automated generation of textual descriptions for audio content, such as spoken language, sound events, or music. This process typically employs deep learning techniques, such as recurrent neural networks, transformer models, and so on, to analyse audio signals and generate coherent captions. By training on large datasets that include both audio recordings and corresponding textual descriptions, these models learn to recognize patterns and contextual meanings within the audio.
Supervisor: Assoc Prof Thanh Thi Nguyen
Voice cloning deepfakes detection using machine learning
This project focuses on identifying and distinguishing between authentic audio recordings and those that have been artificially generated or manipulated. As voice cloning technology advances, creating realistic audio deepfakes has become easier, raising concerns about misinformation and privacy. To combat this, this project aims to develop machine learning models to analyse audio features such as pitch, tone, cadence, and spectral characteristics. These techniques are implemented to detect subtle anomalies that may indicate manipulation, even in high-quality deepfake audio.
Supervisor: Assoc Prof Thanh Thi Nguyen